Managing AI Crawlers: A robots.txt Guide for SG Businesses
- September 30, 2026
- Business Insights
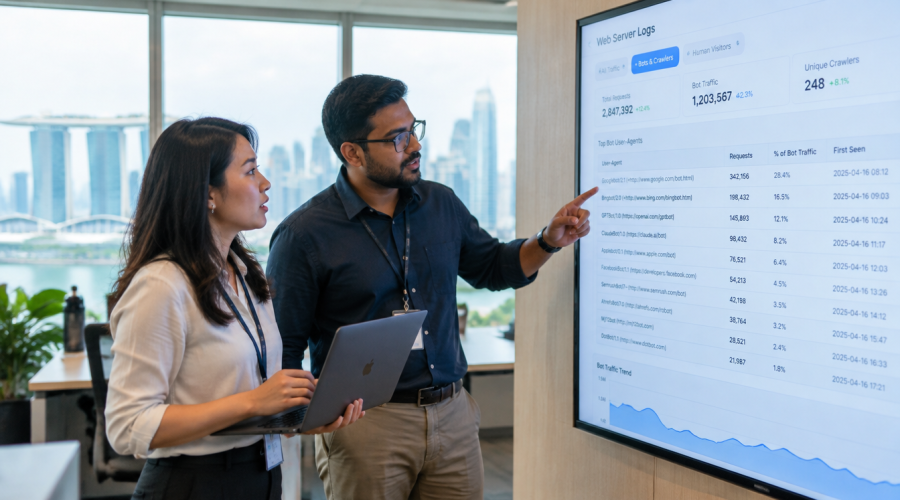
Every time ChatGPT answers a question by citing a Singapore business, or Perplexity quotes a line from a company’s pricing page, a piece of automated software visited that website first and decided it was worth citing. Most site owners have no idea this is happening, because the crawlers doing the reading rarely show up in a Google Analytics report the way a human visitor would.
AI crawlers are not new, but the decision of what to do about them is. GPTBot, ClaudeBot, PerplexityBot and a growing list of others now request pages from almost every public website: some are gathering data to train a future model, others are fetching a page in real time to answer a live question. Singapore businesses reviewing their AI search strategy for 2027 increasingly need an actual policy for these bots, not the accidental one that comes from never having thought about it.
What Are AI Crawlers, and Why Do They Keep Showing Up?
An AI crawler is software that a company such as OpenAI, Anthropic or Perplexity sends out to read the public web, much as Googlebot has done for search results since the 1990s. Instead of building a search index, though, these systems fold the content into a training dataset, or fetch it in the moment to construct an answer to a question typed into a chatbot. Each identifies itself with a distinct user-agent string, which is what lets a site allow one crawler while blocking another instead of treating "AI" as a single switch. Some of the crawlers active on the web right now include:
- GPTBot, OpenAI’s primary crawler for gathering training data
- ChatGPT-User, which fetches a page in real time when someone asks ChatGPT to browse it
- ClaudeBot, Anthropic’s crawler, alongside the related Claude-User agent for live browsing
- PerplexityBot, which indexes pages so Perplexity’s answer engine can cite them
- Google-Extended, a separate signal from Googlebot controlling use in Gemini and AI Overviews
- Bytespider, the crawler operated by ByteDance, TikTok’s parent company
What robots.txt Can and Cannot Do
robots.txt is a plain-text file at the root of a domain that tells visiting bots which parts of a site they may access. A Disallow rule under GPTBot’s user-agent name asks GPTBot not to crawl the pages listed, and that request works only because the crawler chooses to honour it. Reputable AI companies generally respect robots.txt, and OpenAI, Anthropic and Perplexity all publish documentation confirming their crawlers check the file first. Less careful scrapers are under no such obligation, and some simply ignore it.
That gap between a polite request and an enforced rule deserves real attention. Search Engine Journal’s recent guidance on this compares a robots.txt entry to a no-trespassing sign in front of an open gate, while blocking at the server or firewall level works more like a padlock on that gate. It recommends going as high up the server stack as practical, reserving robots.txt alone for the one or two most reputable crawlers, provided someone is actually watching the server logs for violations.
Should Your Business Block AI Crawlers, Allow Them, or Something in Between?
There is no single correct setting here, and treating this as one is where a lot of policies go wrong. The right approach depends on what a business sells, and whether it wants to be quoted by AI search tools such as ChatGPT and Gemini rather than simply protected from them:
- Does the business want AI systems to cite its content? A services firm hoping to be recommended by ChatGPT has the opposite incentive to a publisher protecting subscriber-only content.
- Is bandwidth or server load a genuine concern? Large e-commerce catalogues can see crawl volume from AI bots that smaller brochure sites rarely notice.
- Does the content include pricing, contracts or account pages never meant for public reuse? Those sections deserve blocking regardless of the broader policy.
- Has a competitor or content aggregator been caught scraping material wholesale under an AI crawler’s user-agent? That is a server-level problem, not a robots.txt one.
- Is the business prepared to update its rules as new crawlers appear? A list frozen from a year ago is already missing several bots now active on the web.
A Practical Setup: robots.txt Alongside llms.txt
For most Singapore SMEs, a workable starting point is simple: allow crawlers from AI companies whose product a business wants to appear in, disallow the rest by name, and revisit the file every few months as new bots launch. A snippet blocking a poorly behaved scraper reads as a user-agent line naming the bot followed by a blanket Disallow, while a crawler a business is happy to allow needs no entry at all, since the default is to permit unless told otherwise.
robots.txt and llms.txt solve different problems. robots.txt is a gate, granting or denying access to specific bots. The llms.txt file is closer to a signpost inside a gate that is already open, pointing a visiting AI system toward the most important pages to read first. A site that blocks GPTBot outright gains little from also publishing an llms.txt file for OpenAI’s systems, since the two settings work against each other.
Neither file guarantees results alone. A carefully written llms.txt cannot make AI systems cite a page that says little of substance, and a strict robots.txt cannot stop a scraper that ignores the file entirely. Treat both as the low-cost half of an AI visibility strategy, alongside the harder work of building content that actually earns a citation.
Keep Watching the Server Logs
Because robots.txt only works when a crawler chooses to respect it, publishing the file is the start of a policy, not the end of one. Server access logs will show whether a supposedly blocked bot kept requesting pages anyway, either because it ignored the rule or because a scraper spoofed a legitimate crawler’s user-agent. A quarterly check, alongside the usual technical SEO audit, is generally enough to catch problems early.
Setting a Deliberate Policy
The businesses handling this well in Singapore right now are not necessarily blocking everything, nor letting everything through by default. They have made a deliberate choice, matched to what their content is for, and they revisit it periodically instead of leaving it to whatever a template happened to set years ago.
If you would like a second opinion on how your site currently handles automated visitors, and whether that setup still matches your search goals, feel free to get in touch with our team.
More from our blog
See all posts